Hacker News new | past | comments | ask | show | jobs | submit
Damn people were right about 5.5 being nerfed in preparation for a version release. This is not at all a good look.

- https://news.ycombinator.com/item?id=50422069

I at least didn't see this. I had a baseline evaluation from before Nov 3 on Opus 5.5 medium, so I re-ran it this morning.

Eval context: 30 bug fixes and features evaluated by tests the agent didn't see. Ran on Opus 5.5 at medium effort in Claude Code.

20 of the tasks were last run on Nov 1, twice each. Nov 1 solved 36/40, and today solved 19/20. Thinking tokens per task were 0.95x Nov 1’s and output tokens 0.97x. The one significant change was speed: median time to first token decreased from 3.0s to 1.7s.

Caveats: one run per task today, medium effort only.

loading story #50432273
loading story #50433306
loading story #50431003
loading story #50431865
loading story #50431491
I dunno there are some other nerf trackers that aren't showing a regression: https://github.com/ninjahawk/livenerf
loading story #50431535
loading story #50430784
loading story #50430993
loading story #50431242
loading story #50430730
loading story #50433539
loading story #50430628
I used to be skeptical of nerfing, but as of a week or so ago I've noticed a severe degradation of quality for GPT Astra. It struggled with very simple tasks, and it often failed to follow my instructions.
loading story #50430599
loading story #50431221
loading story #50430703
loading story #50430493
loading story #50430739
loading story #50432059
loading story #50430388
According to our measurements this isn't true. We re-ran Opus 5.5 today on the benchmark we ran in September, with the same prompt and settings. Before and after, side by side: https://playcode.io/blog/macbook-svg-benchmark#reruns

Max, streamed (128K cap): 128,000 tokens, $2.56, empty file, in September and today.

Max, Batch API (300K): 255,957 tokens for $2.56 in September, 243,707 for $2.44 today. The two drawings: https://playcode.io/marketing/assets/static/claude-opus-5-5-... and https://playcode.io/marketing/assets/static/claude-opus-5-5-...
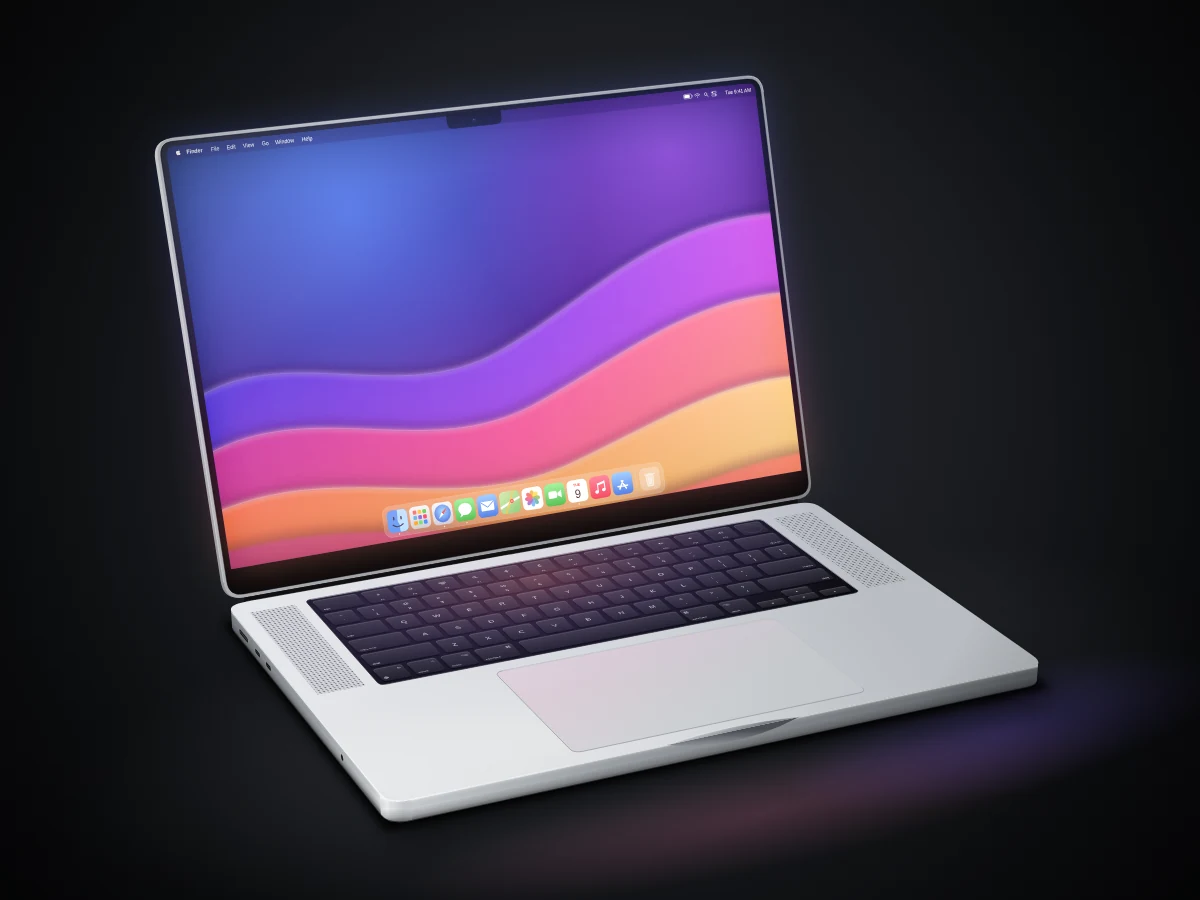
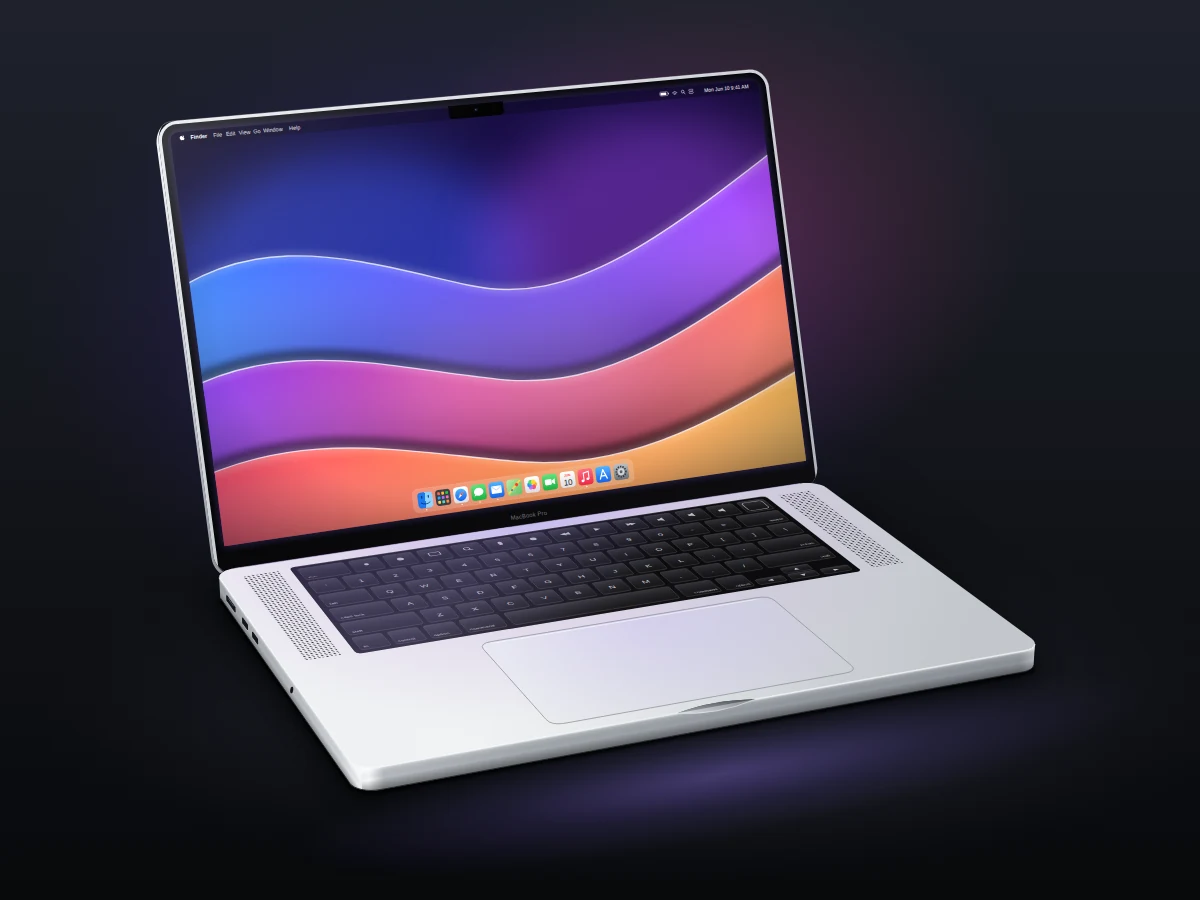
Xhigh: 86,096 tokens for $1.72 in September, 107,333 for $2.15 today.

The Batch API bills half price. Max ran out of the 128K ceiling again, to the token. Given 300K, it drew the same kind of laptop with 5% fewer tokens. Xhigh used 25% more and drew the same kind of laptop. That's inside the noise: 17 identical calls at high ranged from 17,757 to 59,705 tokens.

The model is still the best of everything we've tried. Most likely the next best would be Fable 5.2. But we don't like Fable because essentially the result is the same, just the price is higher. Its medium and high are close to what Opus 5.5 Max had, but the price is higher.

(I run Playcode, an AI app builder. We benchmark every model before we add it.)

I'm guilty of suspecting this.

If this turns out to be accurate, I think that would be a pretty unethical thing for Anthropic. Even if it is just a "we had to allocate compute to this new model release".

It should be fraud to swap out the model. We need a term for this, something like a bait-and-switch.

loading story #50433605
loading story #50431115
loading story #50430907
This happened last time too with Opus 5.5 (released September 22): https://news.ycombinator.com/item?id=49789224
idk, it hasn't felt nerfed at all to me, and it's not like i'm just doing trivial CRUD webapps either. opus 5.5 is very successfully porting my phone to postmarketos. claude just got the touchscreen up and working (and made a little program for me to test it, and it's legit).
Benchmarks don't do a good job at capturing the difference in quality of frontier models over smaller models.

Opus 5.5 was so good that if it wasn't nerfed - at least just looking at the benchmarks - the difference in cost here does not seem to justify using this for anything besides design and review.

That's like maybe 1% of total token usage for SWE BUT a better design can have enormous benefits, so it's almost always worth using the best model for that.

Cost per task

Fable 5.1 Max $11.46

Fable 5.2 Max $44.70

I don't have a formal benchmark, but daily work (coding mostly, plus some complex architecture design and review) has had consistent outputs today for me. No noticeable nerf from my perspective. I definitely took notice in some past instances, but if they nerfed Opus 5.5, then I guess it was just so good that I was nowhere near its limits.
{"deleted":true,"id":50430670,"parent":50430261,"time":1794253044,"type":"comment"}
Can you share some evidence?
> Damn people were right about 5.5 being nerfed in preparation for a version release. This is not at all a good look.

Anthropic does this time and time again, unserious company

loading story #50430720
I'm not surprised at all that they might be doing shady shit, my free request was used up in less than 7 minutes and said pay to continue, no thanks. I've paid for monthly before, never again I don't care how good the model is. I asked about the extreme limited usage in their discord and got banned, not a good look. You don't have a way to measure what you're actually paying for and they can change it at any time.
OpenAI did the same and that was the end of it for me. Completely murderded 5.3 and rug pull on cost.
No they weren't. Models are not "nerfed".
loading story #50432213
In a normal world you are not allowed to degrade the service during your agreed and paid contract. You would get sued. Apparently this is perfectly fine in this current world.
{"deleted":true,"id":50431454,"parent":50430261,"time":1794255816,"type":"comment"}
No it’s not nerfed. Another poster said it the best, your dopamine receiptors are nerfed after the new model hype wears off
loading story #50435581
A friend who doesn't follow these news suddenly told me he felt Claude was doing worse the past week. I bet him there was a new model version coming up within days. It's like clockwork at this point, no matter what deniers say. I got a beer out of it at least :)
{"deleted":true,"id":50431433,"parent":50430261,"time":1794255731,"type":"comment"}
People have been complaining about how the models are nerfed non-stop for two years. A stopped clock is right twice a day.
{"deleted":true,"id":50430450,"parent":50430261,"time":1794252393,"type":"comment"}
yeah, we need to make sure we don't get stuck with these two evil corps. Dario is really the worst. Plays the drama queen but he is very hard in all things dark(i.e. dark patterns).
But, it’s okay they do it because they charge less when it happens.

Right?

{"deleted":true,"id":50431247,"parent":50430261,"time":1794255107,"type":"comment"}
It's been a mess over the last week or so. Went from being the best model I've ever used to utter dogshit that can't complete any task. It's very obvious with the Advisor pattern, where before when it chatted to Fable 5.1 there were small tweaks and so. No every time Fable comes back catching a ton of problems and bugs with Opus 5.5

Fuck Anthropic.

Is this voodoo? Every time someone makes this claim I'm left scratching my head wondering what the hell they're talking about. Either I'm not very perceptive, or these claims are subjective hand-waving.
This has happened every single time for the past year, why are people surprised? This is all so that the new models can look better on the benchmarks.
It's a good pattern to detect for perhaps.
It's not true. People need to stop believing these conspiracy theories.
i thought i was going crazy. last week, claude went from having good judgement to doing all sorts of stupid stuff. what a shame.
for me opus 5.5 was acting kind of dumb, like forgetting basic stuff he was nailing last week
loading story #50431780
loading story #50433594
Another reason we need to democratize local models.
I literally hit the desk with an open hand yelling I KNEW IT
It gets worse. You might wonder "why now"? Well ... this happened 2 days ago:

https://x.com/follistatindev/status/2119129611510383014

With early handouts of Qwen4 starting to be reported 5 days ago ... so if they're good, they would have had some hours to evaluate Qwen4 against Claude 5.5 and, then or right after was when Anthropic decided to put out 5.2 ...

So yeah ... benchmaxxing and all that. BUT nevertheless, the published results seem to say that Qwen4-Max appears to match Opus 5.5 on some benchmarks, and Qwen4-27B (probably by going even harder than Qwen3.8-27B on thinking/inference time compute) can beat Sonnet 5.5 on some things.

I guess they're not taking any chances. Keep in mind that Anthropic has declared they have non-public models (it's in their IPO filing). These are referred to by the shorthand names Model 2, Model 3, and Model 4. Essentially 4 is better than 3 is better than 2.

Fable 5.2 is "2.5" so to speak. So Anthropic was holding back, but not anymore. And now they can dial the performance up once more with what they have ready, and probably once more after that.

loading story #50431266
loading story #50430564
loading story #50430466