Hacker News new | past | comments | ask | show | jobs | submit

Claude Fable 5.2 and Mythos 5.2

https://www.anthropic.com/claude-fable-and-mythos-5-2
loading story #50430766
loading story #50439835
loading story #50441637
loading story #50430829
loading story #50431037
loading story #50439556
> Our first formalization of Fermat’s Last Theorem, performed by an unreleased research version of Claude, took 11 days. It relied on a purpose-built harness along with guidance from a human researcher. By contrast, a team of 1,000 Fable 5.2 agents fully formalized the theorem in just 30 hours, with minimal human intervention. Fable 5.2 started from minimal prompts, built its own ways to coordinate, and used no mathematical references, only a list of intermediate theorem statements to score progress. It needed one-third of the action tokens as our first formalization and produced a proof seven times shorter. As can be seen in the figure below, Opus 5.5 (with the same 1,000-agent setup) completed only 26% of the formalization in 18 hours, and barely made any more progress after 30.

Most people don't really have intuitions on what it means to push the frontier now (because AI has surpassed everything they are good at, for example, coding). We are truly inside the singularity (using Kurzweil's definition, slightly paraphrased - the time when technology progresses so fast no one can keep track with it).

loading story #50432151
I think this is upside down.

AI is actually still really bad at architecture. It produces very good localized code, like an auto complete. It produces so much of it, that it can be overwhelming, but it's not remotely better than the equivalent aka an infinite number of talented humans doing the work.

The scale of it (aka 'make me a video game') is daunting and I think misinforming our intuition as to what is going on.

LLMs are brute forcing outputs and attacking math problems is not a singularity, it's just more compute.

What we are witnessing is the ability for machines to use fuzzy concepts, instead of very strict code, which allows it to map into a much greater variety of things, aka code, pdfs, web - and crunch/compute the content.

It's just compute.

loading story #50437695
In the end, if the singularity arrives, it will be just compute too.
loading story #50435748
loading story #50434548
loading story #50434341
loading story #50436197
loading story #50430723
loading story #50431080
loading story #50433862
loading story #50433226
loading story #50430491
loading story #50432267
loading story #50432294
I would imagine Anthropic is hitting a wall on the number of simultaneous agents that can be useful on a task and are working on increasing that maximum.

I would assume if they could get twice as much progress by using 10000 simultaneous running fable instances instead, their brief would state that.

IMO, it is very interesting and also very alarming. At some point the barrier to the exponential progress is the amount of computation available. The average human is limited in the number of 'human instances' he or she can interface with at one time.

if 1000 fable instances is better than any human at a task, how about 1 million instances running? Much easier than finding and hiring and coordinating 1000 extremely productive and intelligent human beings. Much cheaper too, it appears.

We are very close to some very scary things happening. I just recently came to terms with the fact that an AI could code and manage coders faster and better than me, I don't think anyones is ready for what is about to happen.

It depends on the type of task. There was an interview on Dwarkesh with an OpenAI researcher and he said that massive multi-agent swarms can increase capability on some problems that are very parallelizable, but there are diminishing returns. But not all tasks can be parallelized like that.

Where it gets scary is the fact that efficiency is going up 10x per year, so the cost of running 1000 agents will cost the same as running 1 agent in 3 years if the trend holds.

loading story #50432853
loading story #50435986
loading story #50431882
loading story #50430443
loading story #50430958
loading story #50435452
loading story #50438326
loading story #50430827
loading story #50434469
loading story #50431174
loading story #50430680
loading story #50432156
loading story #50430632
loading story #50432389
loading story #50430636
loading story #50430590
loading story #50430228
loading story #50433004
loading story #50435571
loading story #50430962
loading story #50430085
loading story #50432097
loading story #50436100
loading story #50430200
loading story #50451460
loading story #50433540
Setting aside the comments about nerfing, do normal mortals out there have workflows that really require Fable/Mythos and don't just work fine on Opus 5.5?

I've been using Opus 5.5 on xhigh for some decently aggressive software development on a ~125k-line project, and it has been fine for me. I'm not really willing to dive into a "rewrite the whole project, don't make any mistakes" level of refactoring. I'm not looking to try to prove Fermat's Last Theorem myself. Is there anything that I'm truly missing?

loading story #50431374
I’ve found that Fable is good when the model intuition really matters. For instance, picking model architecture in a machine learning problem. Opus will grind the implementation just fine, but having intuition for picking a good research direction is better with fable
loading story #50431958
loading story #50434363
loading story #50432039
loading story #50432646
loading story #50433611
loading story #50431140
loading story #50432291
loading story #50438069
loading story #50431474
loading story #50431039
loading story #50431403
> do normal mortals out there have workflows that really require Fable/Mythos and don't just work fine on Opus 5.5?

I usually have Fable review what Opus produces. The edits are almost always valuable. For complex or high-stakes work, too, I'll have Fable review and revise my prompt before passing it to Opus and Sonnet swarms.

loading story #50431440
loading story #50430849
loading story #50432487
loading story #50432418
loading story #50433790
loading story #50435775
loading story #50434507
loading story #50431536
loading story #50431225
loading story #50449591
loading story #50430241
loading story #50449121
loading story #50431752
loading story #50436112
loading story #50441779
loading story #50435720
loading story #50431370
loading story #50437677
loading story #50432816
Here's the benchmark: https://playcode.io/blog/macbook-svg-benchmark#compare

If we compare medium or high, then yes, Fable 5.2 is significantly better than Opus 5.5. But it's better not because it's much smarter, but because you can see it's allowed to spend more tokens. At high, Fable 5.2 wrote 76,158 tokens for $3.05. Opus 5.5 wrote 19,767 for $0.40. If you compare by token count, it's just spending more.

The most interesting one was to compare them at max. Streamed, Fable 5.2 spent the whole 128K output ceiling on thinking and returned nothing. Given 300K on the Batch API, it finished at 250,082 tokens. Opus 5.5 Max needed 255,957.

It turns out it's basically the same as Opus 5.5 Max. I don't see much difference. There's a little bit of a difference, but I think Opus 5.5 actually drew slightly better and is twice as cheap: $5.12 against $10.00 at the standard price. If you look closely, the icons are extremely similar. Fable 5.2: https://playcode.io/marketing/assets/static/claude-fable-5-2... Opus 5.5: https://playcode.io/marketing/assets/static/claude-opus-5-5-...
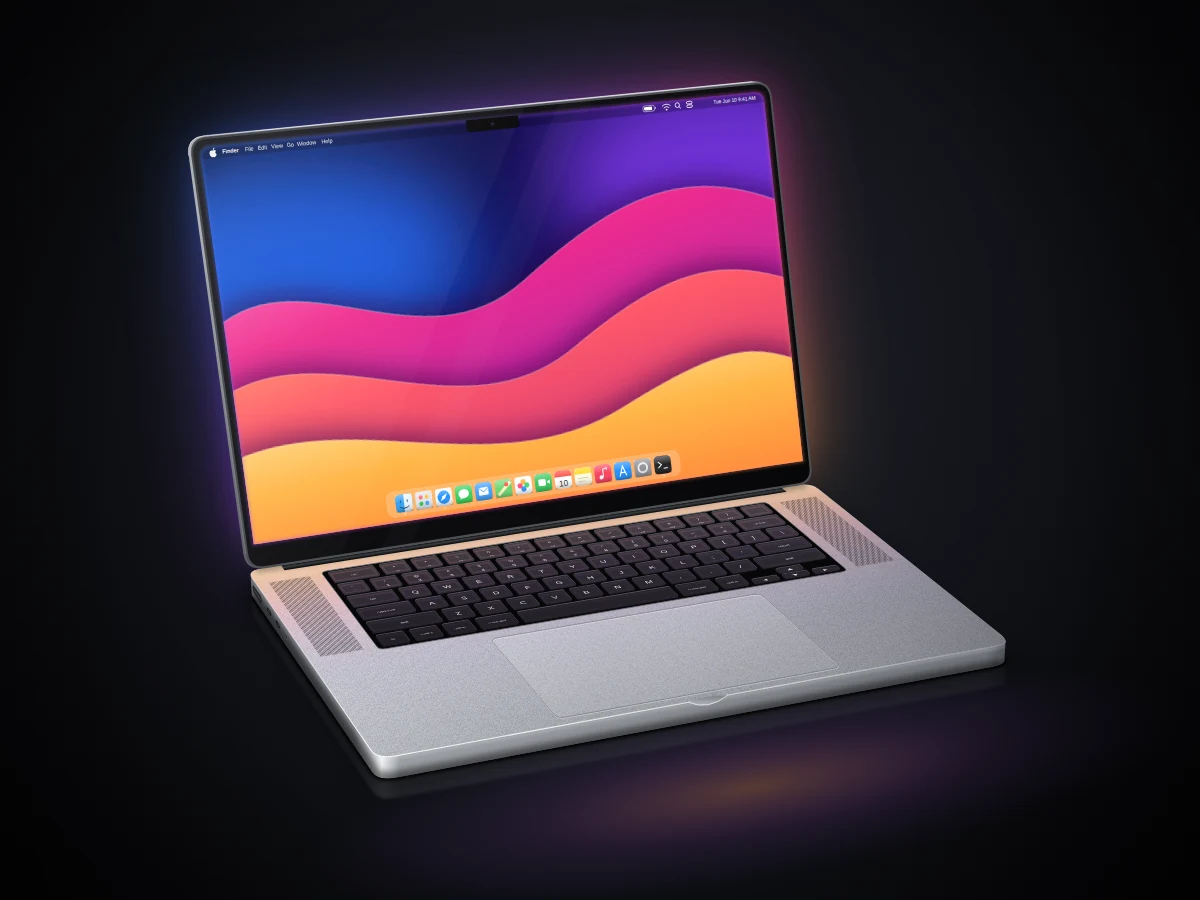
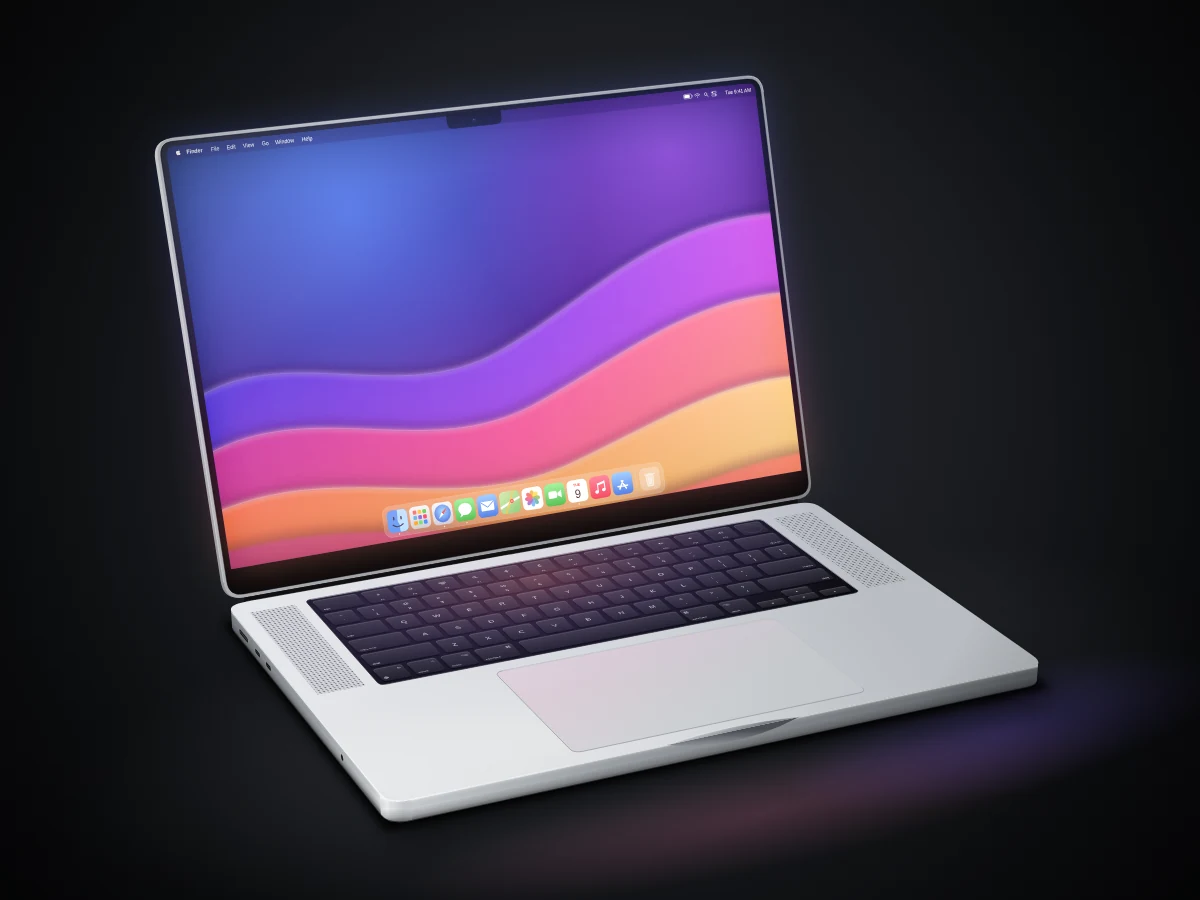
It really looks like they're just tuning the effort level, that's basically it. At different effort levels, they just gave it more context, and the model got smarter.

For now, my recommendation is still to do everything on Opus 5.5 Max. The model won't write that many tokens in agent mode. It only does that when there are no tools at all.

loading story #50434848
loading story #50431336
loading story #50430155
loading story #50450964
loading story #50430239
loading story #50430097
Doubling Remote Labor Index (RLI) - at 41.3% compared to around 20% for the other models - I wonder what kinds of new agentic work this is going to unlock.
loading story #50442801
loading story #50431343
loading story #50431089
loading story #50442613
loading story #50437480
loading story #50430350
loading story #50442674
loading story #50437942
loading story #50438393
loading story #50435602
{"deleted":true,"id":50442329,"parent":50429068,"time":1794326960,"type":"comment"}
loading story #50432552
loading story #50441116
loading story #50441696
loading story #50439068
loading story #50434753
loading story #50431994
loading story #50430089
loading story #50431220
loading story #50431471
loading story #50435303
loading story #50431327
https://artificialanalysis.ai/#intelligence-efficiency-tabs this is the chart that matters for most of poor developers and companies. Pareto for a given intelligence index and looks like only openai is across the quadrant with muse at the bottom. They have really cooked efficient models!
loading story #50431222
loading story #50435366
loading story #50441998
loading story #50437524
loading story #50430098
loading story #50430938
loading story #50435235
loading story #50430567
Damn people were right about 5.5 being nerfed in preparation for a version release. This is not at all a good look.

- https://news.ycombinator.com/item?id=50422069

loading story #50430746
loading story #50430482
loading story #50430349
According to our measurements this isn't true. We re-ran Opus 5.5 today on the benchmark we ran in September, with the same prompt and settings. Before and after, side by side: https://playcode.io/blog/macbook-svg-benchmark#reruns

Max, streamed (128K cap): 128,000 tokens, $2.56, empty file, in September and today.

Max, Batch API (300K): 255,957 tokens for $2.56 in September, 243,707 for $2.44 today. The two drawings: https://playcode.io/marketing/assets/static/claude-opus-5-5-... and https://playcode.io/marketing/assets/static/claude-opus-5-5-...
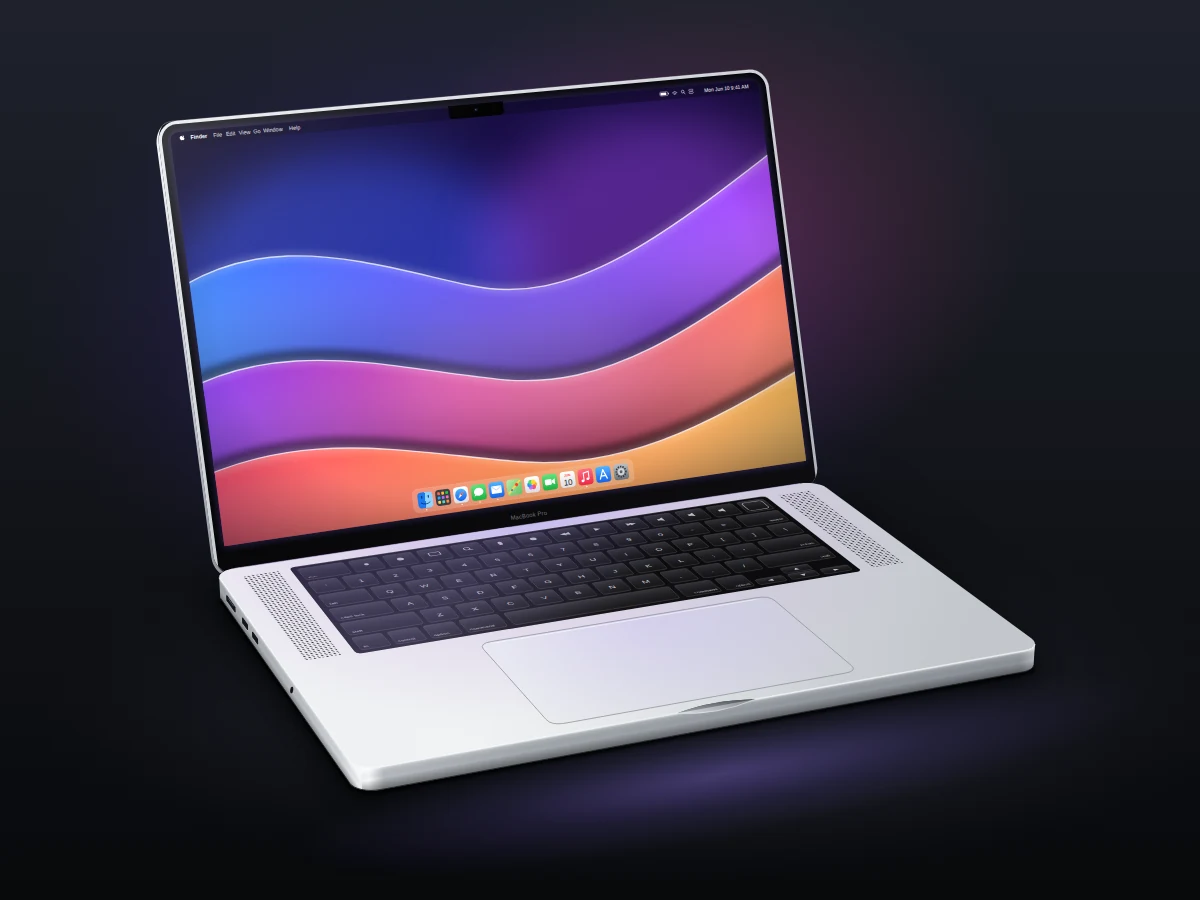
Xhigh: 86,096 tokens for $1.72 in September, 107,333 for $2.15 today.

The Batch API bills half price. Max ran out of the 128K ceiling again, to the token. Given 300K, it drew the same kind of laptop with 5% fewer tokens. Xhigh used 25% more and drew the same kind of laptop. That's inside the noise: 17 identical calls at high ranged from 17,757 to 59,705 tokens.

The model is still the best of everything we've tried. Most likely the next best would be Fable 5.2. But we don't like Fable because essentially the result is the same, just the price is higher. Its medium and high are close to what Opus 5.5 Max had, but the price is higher.

(I run Playcode, an AI app builder. We benchmark every model before we add it.)

loading story #50430555
loading story #50431069
loading story #50430661
loading story #50430874
loading story #50431894
loading story #50431444
loading story #50430670
loading story #50431740
loading story #50430406
loading story #50430909
loading story #50433080
loading story #50430808
loading story #50431482
loading story #50431454
loading story #50430538
loading story #50433162
loading story #50431433
loading story #50430822
loading story #50430450
loading story #50430935
loading story #50430624
loading story #50431247
loading story #50433492
loading story #50433134
loading story #50431154
loading story #50430973
loading story #50430507
loading story #50433874
loading story #50431746
loading story #50430745
loading story #50430573
loading story #50430419
loading story #50434685
loading story #50430409
loading story #50439639
loading story #50430511
loading story #50431435
loading story #50432159
loading story #50440315
loading story #50432927
loading story #50434027
This is the first frontier model release by them that I am not that moved or eager to go use it, will likely stay on Opus 5.5 or other frontier models.

I am curious as to why they launched this one and why now.

loading story #50434465
loading story #50434538
loading story #50437895
loading story #50436911
loading story #50430943
loading story #50436915
loading story #50429993
loading story #50430137
loading story #50431358
loading story #50438530
loading story #50430925
loading story #50430741
loading story #50430287
loading story #50433738
loading story #50436358
loading story #50436244
loading story #50437347
loading story #50430248
loading story #50430931
loading story #50431056
loading story #50430174
loading story #50440738
loading story #50435037
loading story #50430318
loading story #50432707
loading story #50439726
loading story #50433863
loading story #50437947
loading story #50430126
loading story #50437346
loading story #50436677
loading story #50433410
loading story #50430574
loading story #50430410
loading story #50438303
loading story #50432092
loading story #50435296
loading story #50430644
loading story #50430826
loading story #50430544
loading story #50431688
loading story #50437376
loading story #50435974
loading story #50439200
loading story #50438531
loading story #50438147
loading story #50437778
loading story #50433371
loading story #50435353
loading story #50430065
loading story #50440368
loading story #50435151
loading story #50430692
loading story #50431931
loading story #50431940
loading story #50430883
loading story #50430660
loading story #50430229
loading story #50430732
loading story #50430707
loading story #50432238
loading story #50431150
loading story #50430756
loading story #50430504
loading story #50434904
loading story #50434639
loading story #50441927
loading story #50444608
loading story #50438335
loading story #50438375
loading story #50431516
loading story #50434959
loading story #50431662
loading story #50431508
loading story #50442809
loading story #50436239
loading story #50436368
loading story #50430367
loading story #50437282
loading story #50436889
loading story #50430214
loading story #50430254
loading story #50436180
loading story #50436193
loading story #50430243
loading story #50431757
loading story #50430233
loading story #50429990
loading story #50430267
loading story #50430588